AI Visibility Dashboard (the "AI Visibility Report" screen)
What this is for, in one sentence: this is your scoreboard — the four numbers that summarize how visible your brand is inside AI answers, across all five platforms, over time.
When to come here: whenever new results land. Zicy now tracks on a daily, weekly, or monthly view, so you can glance at day-to-day movement or step back to the longer trend. This is the screen you check when results update, the screen you screenshot for a boss, and the starting point for every “why?” question (the answers to which live in the Diagnose modules).
We continue with Sarah at MenuPilot. Her dashboard appears in Setting Up Zicy for the First Time (GS-01) — this article goes deeper on how to actually read it.
The four numbers, and how to judge them
Section titled “The four numbers, and how to judge them”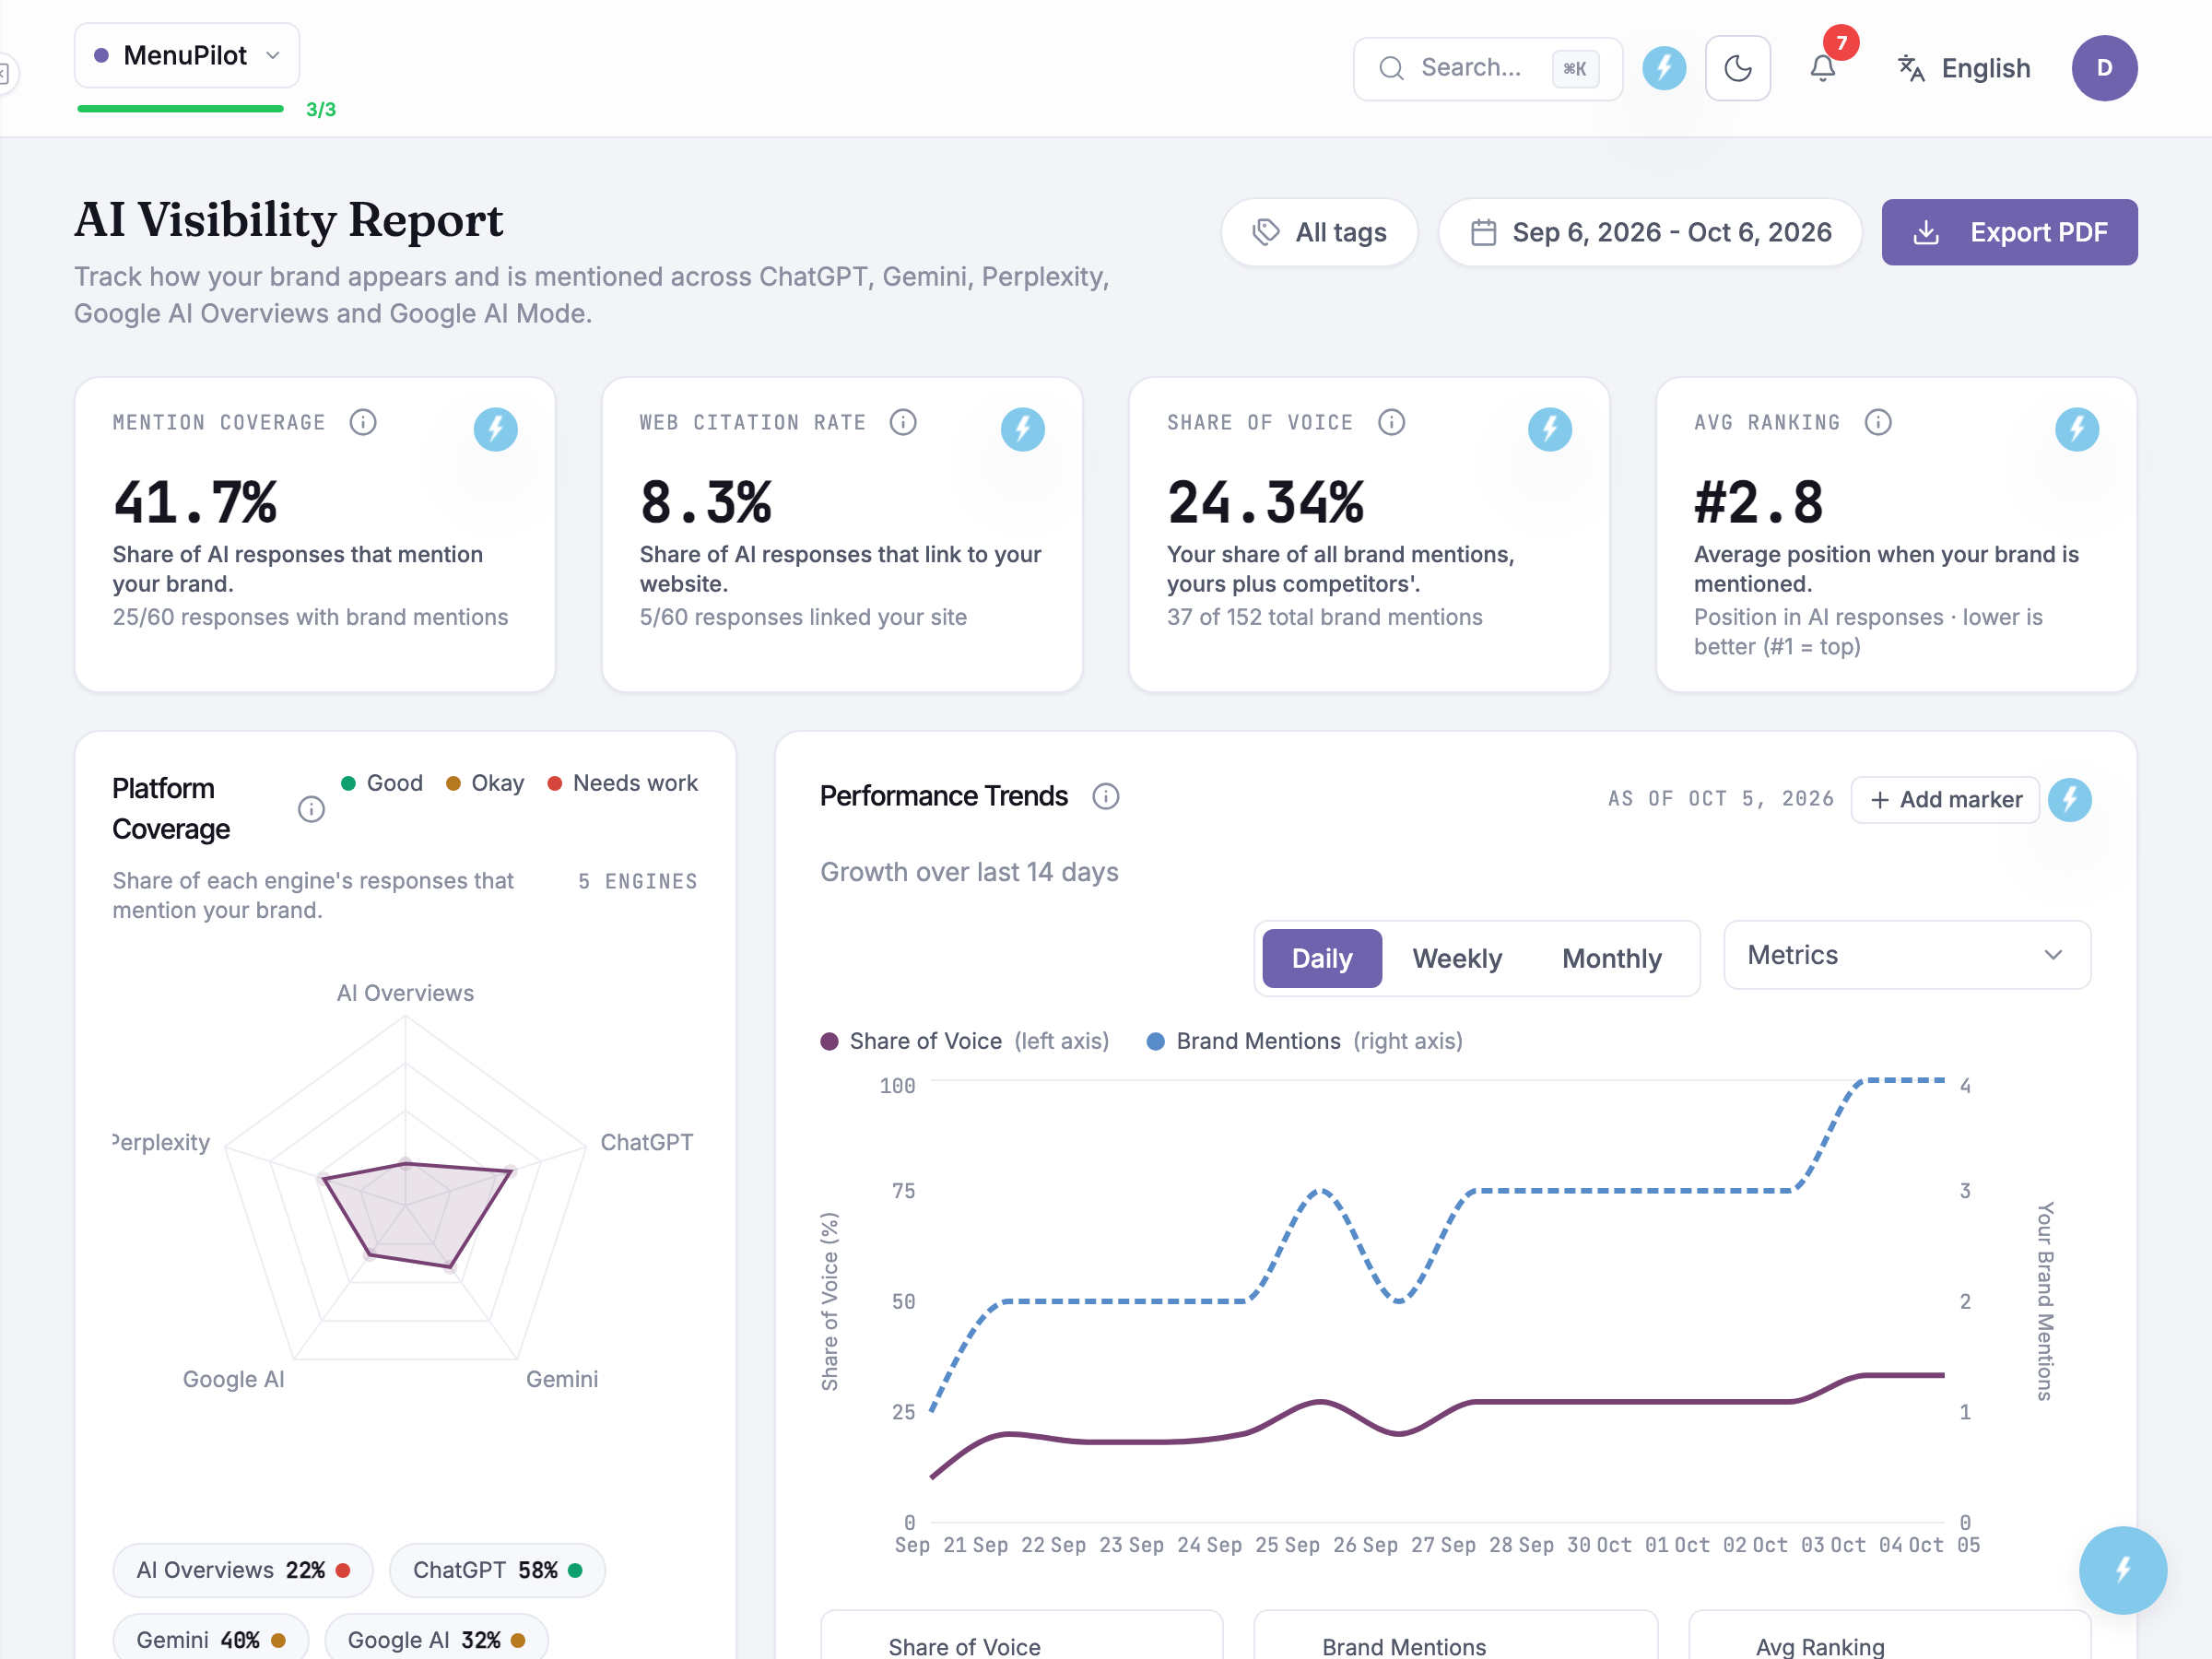
Each KPI card shows four things: the value, the count behind it, the change versus the prior period, and a plain-English benchmark chip — Good, Okay, or Needs work — so you get a read on the number without needing a data background. The one-line definition now sits directly under the number (no hunting required); the little “i” opens the fuller explanation:
1. Brand Mention Coverage — % of AI answers that named you at all. Sarah’s 41.7% = 25 of 60 responses.
2. Web Citation Rate — % of answers that linked to your site. Expect this to be much lower than coverage — being named is common, being linked is rare. A citation rate at 1/3 to 1/5 of your coverage is a normal shape, not a problem. (Coverage and citation are two independent measurements — if they ever read exactly the same, that’s a small-sample coincidence, not one number copying the other.)
3. AI Share of Voice — your share of every brand mention across all answers. Sarah’s 24.3% = 37 of 152 mentions.
4. Average AI Ranking — your average position when AI lists options. Lower is better — and so a falling ranking number is good news. Sarah’s move from 3.0 → 2.8 is an improvement.
“But is my number good?”
Section titled ““But is my number good?””The benchmark chip on each card gives you the quick read. For the fuller picture, three comparisons mean the most:
- You vs. your competitors — the same numbers for your tracked rivals live on the Competitive AI Performance screen (M-05). Being at 41.7% coverage means little; being second of five brands means a lot.
- You vs. last period — direction beats level. A brand moving 20% → 30% is winning; a brand parked at 60% may be coasting on old strength.
- Coverage vs. Share of Voice together — high coverage + low share of voice = you’re often mentioned but rarely the star of the answer. That combination points you straight at Battlegrounds in Key Topics (M-09).
The radar chart (per-engine coverage)
Section titled “The radar chart (per-engine coverage)”The five-cornered chart shows your coverage on each platform. Lopsided shapes are normal — Sarah is strong on ChatGPT (58%) and weak on Google AI Overviews (22%). Rather than reading a lopsided radar as failure, read it as a targeting map: each engine trusts different sources, and the Citation Analysis module (M-10) shows which sources move the engine you’re weakest on.
Performance Trends — daily, weekly, or monthly
Section titled “Performance Trends — daily, weekly, or monthly”The trends chart plots your KPIs over time. Use the daily / weekly / monthly toggle (top right of the panel) to change the grain:
daily— one point per tracking cycle, since Zicy now tracks daily by default. Best for spotting the effect of a launch or a PR hit quickly.weekly— rolls the daily runs up into one point per week; smooths day-to-day noise for the cleanest view of a real trend.monthly— the long arc, for reporting and reviews.
Two honest rules for reading trends, whichever grain you pick:
- Mark your events on the chart. The chart now supports event markers — click Add marker to note a campaign launch, PR push, or a prompt-set change, and Zicy also drops automatic markers for things like a prompt-set addition (you’ll see a note such as “Prompts added” on the relevant date). Connecting a metric move to a real-world action is the whole game — especially if you’ll ever need to prove a campaign worked.
- Keep your prompt set stable if you want a clean trend. Adding or removing prompts changes what’s being measured — numbers can jump purely because the questions changed, not because your visibility did. When Sarah added 3 pricing prompts, her blended numbers shifted; that’s composition, not performance. The auto-marker on that date makes the cause obvious at a glance.
The chart plots metrics on two clearly labelled axes — Share of Voice (%) on the left, Brand Mention (count) on the right — with a legend mapping each line to the axis it uses, so a line that looks like it disagrees with a percentage is simply reading the other scale.
Filters: slicing the dashboard
Section titled “Filters: slicing the dashboard”Date range — compare periods; the “vs prior period” deltas on the KPI cards follow your selection.
Tag filter — the payoff for tagging your prompts. Selecting a tag recalculates the entire dashboard in place for just those prompts, and shows the active filter as a removable chip:
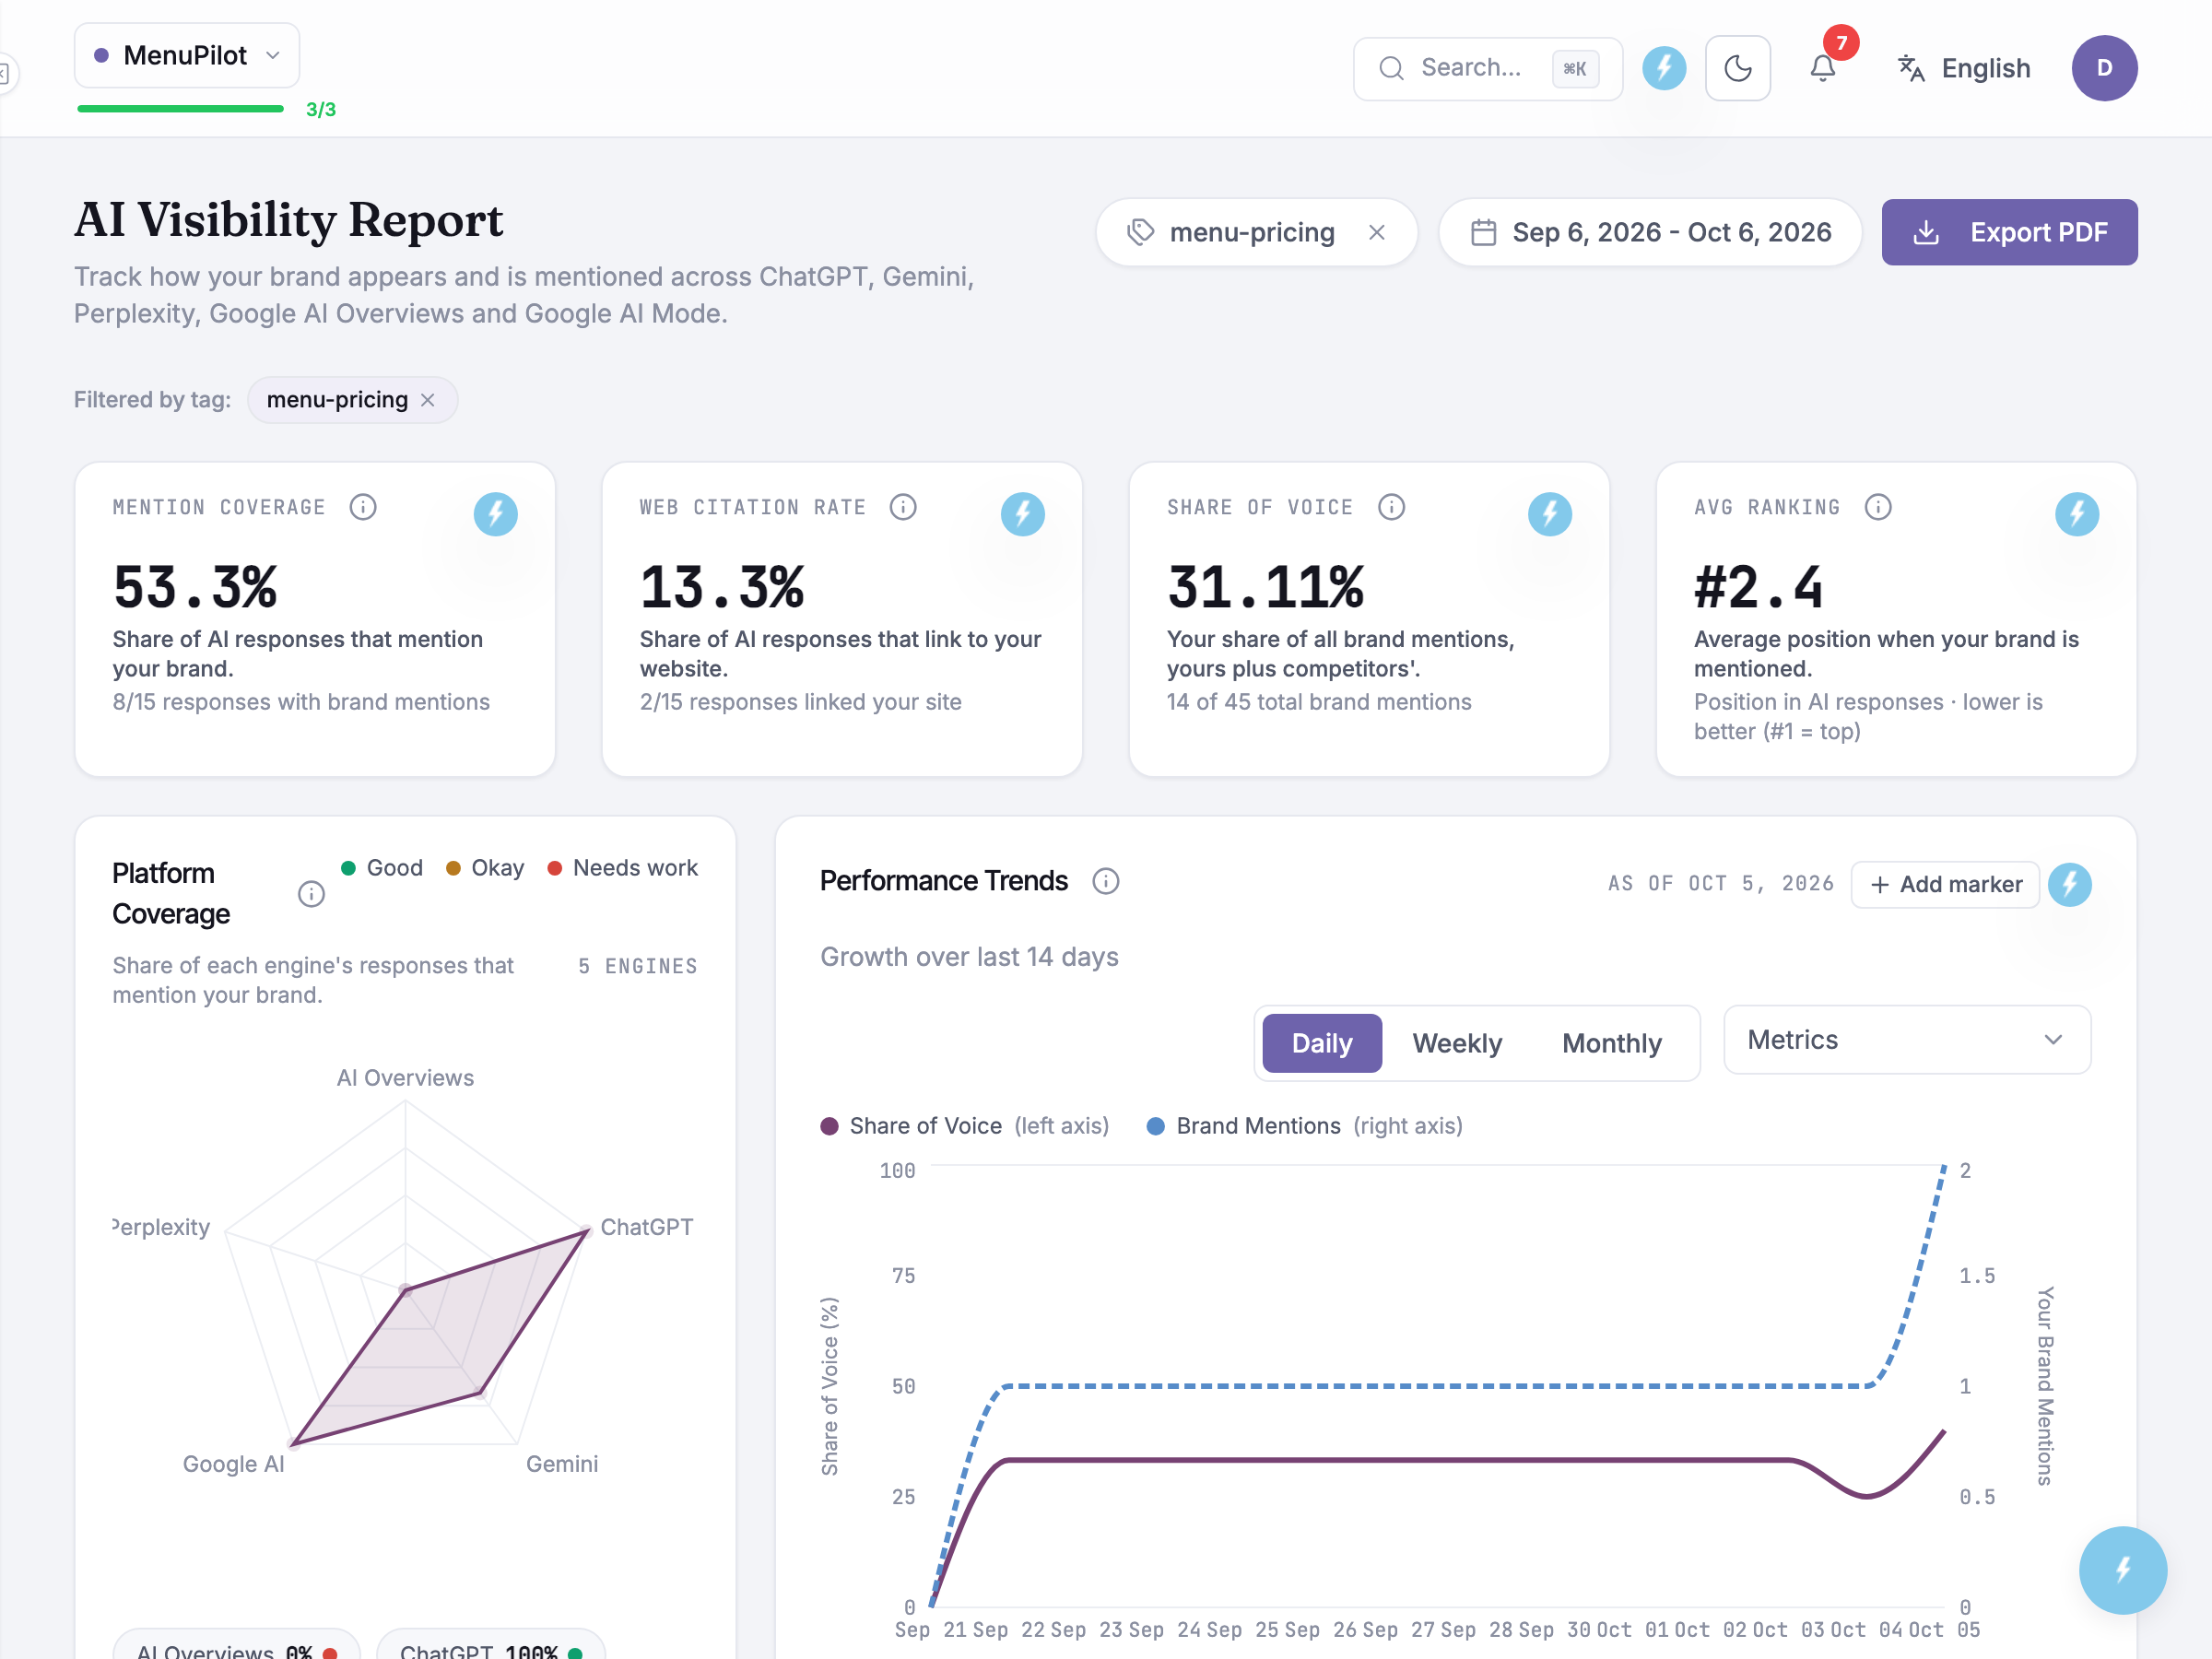
The blended dashboard says Sarah’s coverage is 41.7%; filtered to pricing questions only, it’s 53.3%. Same brand, different question sets, honestly different answers — this is how you find out where you’re strong instead of settling for one average. If your tags exist but this filter feels useless, your tags are too broad; see the tagging system in GS-02.
The sentiment score and competitive panel
Section titled “The sentiment score and competitive panel”The Brand Sentiment panel gives the one-glance answer to “does AI speak well of us?” It reads the tone of the tracked answers that mention your brand, and everything in it is scoped to the brand you are viewing. If your brand name collides with another company’s, descriptors attributed to that company are removed rather than shown as yours.
The headline is a number out of 100, with a band pill below it: Very positive (81 to 100), Positive (61 to 80), Neutral (41 to 60), Negative (21 to 40) or Very negative (0 to 20). The band always matches the number. When a score sits below Positive, the panel adds the line Positive starts at 61, so you can see how far away it is.
The Competitive Landscape table and Competitor Sentiment Profiles use the same bands.
The score is built only on your mentioning responses: the tracked answers that actually talk about your brand. The caption under the score shows how many that is. An answer that never mentions you carries no tone to measure, so it isn’t counted. When the count is small, each mention moves the number more.
A brand-new or thinly tracked profile reads “Not enough data yet” instead of a score, with the reason below it, such as “Not enough mentions yet” and how many you have so far. Sentiment needs at least 3 scored mentions, so give a new profile a few periods before treating its tone as a finding.
The sentiment breakdown shows the share of positive, neutral and negative descriptors AI used about your brand. A healthy profile usually has a positive lead, a substantial neutral middle (much of what AI says about any brand is simply descriptive) and a thin negative tail worth reading closely.
Below the score, two tables list the Positive Descriptors and Negative Descriptors AI repeats about you, each with its mentions and share. Positive descriptors are your earned vocabulary, the strongest raw material for your own pages and positioning. If a column is empty, the panel says why, usually that no descriptor repeated often enough to list.
For each negative descriptor, ask first whether it is a fact problem or a perception problem. A descriptor such as “pricing concerns” that sits next to a wrong price in Brand Intelligence is a wrong fact, so fix the fact and the descriptor follows. A descriptor with no wrong fact behind it, such as “learning curve”, is real perception, addressed with content and product rather than corrections. Read the words before you react to the number: a new descriptor appearing tells you more than a score moving two points.
To see the same score and descriptors for each tracked rival, use the Avg Sentiment (score) and Top Descriptors columns in the competitive table, or open Competitor Sentiment Profiles on the Competitive Landscape page.
The Competitive Landscape panel previews you against your tracked rivals, with a “YOU” badge on your own row; the full head-to-head table is Competitive AI Performance (M-05).
Google Maps Recommendations / Local Map Pack. For tracked local-intent prompts, the dashboard adds a panel below Tracked Prompts that lists the prompts for which Google showed a map pack, and who currently appears in it.
Each row gives the Prompt, a Target Business (Y/N) column showing whether your business is in the pack, #1, #2 and #3 columns naming the businesses Google shows in each position (yours highlighted), and a Google Business Profile column with a View GBP Dashboard link.
Only prompts with an actual map pack result get a row, and the whole panel stays hidden if none do. A prompt that is local but unchecked, or checked with nothing found, doesn’t appear. Check or re-check a prompt from its own page, covered in Per-Prompt Results.
Export PDF (top right) builds the board-ready report from what you’re looking at — covered in full in the Exporting Client Reports article.
Common questions
Section titled “Common questions”My numbers jumped right after I added prompts — did something happen? Probably not in the market: you changed the measurement. New prompts change the mix of questions, so every blended number recalculates. Look for the automatic “Prompts added” marker on the trend chart at that date, and judge the new baseline after a stable period.
Average Ranking shows “—”. Broken? No — “—” means there were no mentions to rank in the selected period/filter. No mentions, no position. It fills in as soon as you’re named somewhere.
Should I read the daily or the weekly view? Daily is great for reacting quickly to a launch; weekly is the honest read of a trend. When in doubt, decide with weekly and investigate with daily.
Which number should I report to my boss? Lead with Share of Voice (the competitive one) plus its trend, then coverage. Better yet: export the PDF (M-15), which packages all four with plain-English definitions.
What to do next
Section titled “What to do next”- Numbers lower than a rival’s? See exactly where: Competitive AI Performance (M-05).
- Wondering which questions drive a number? Open the receipts: Per-Prompt Results (M-03).
- Ready to show someone? Exporting Client Reports.
- Not sure what a number means? Click the lightning icon on any panel to use Ask Zicy.